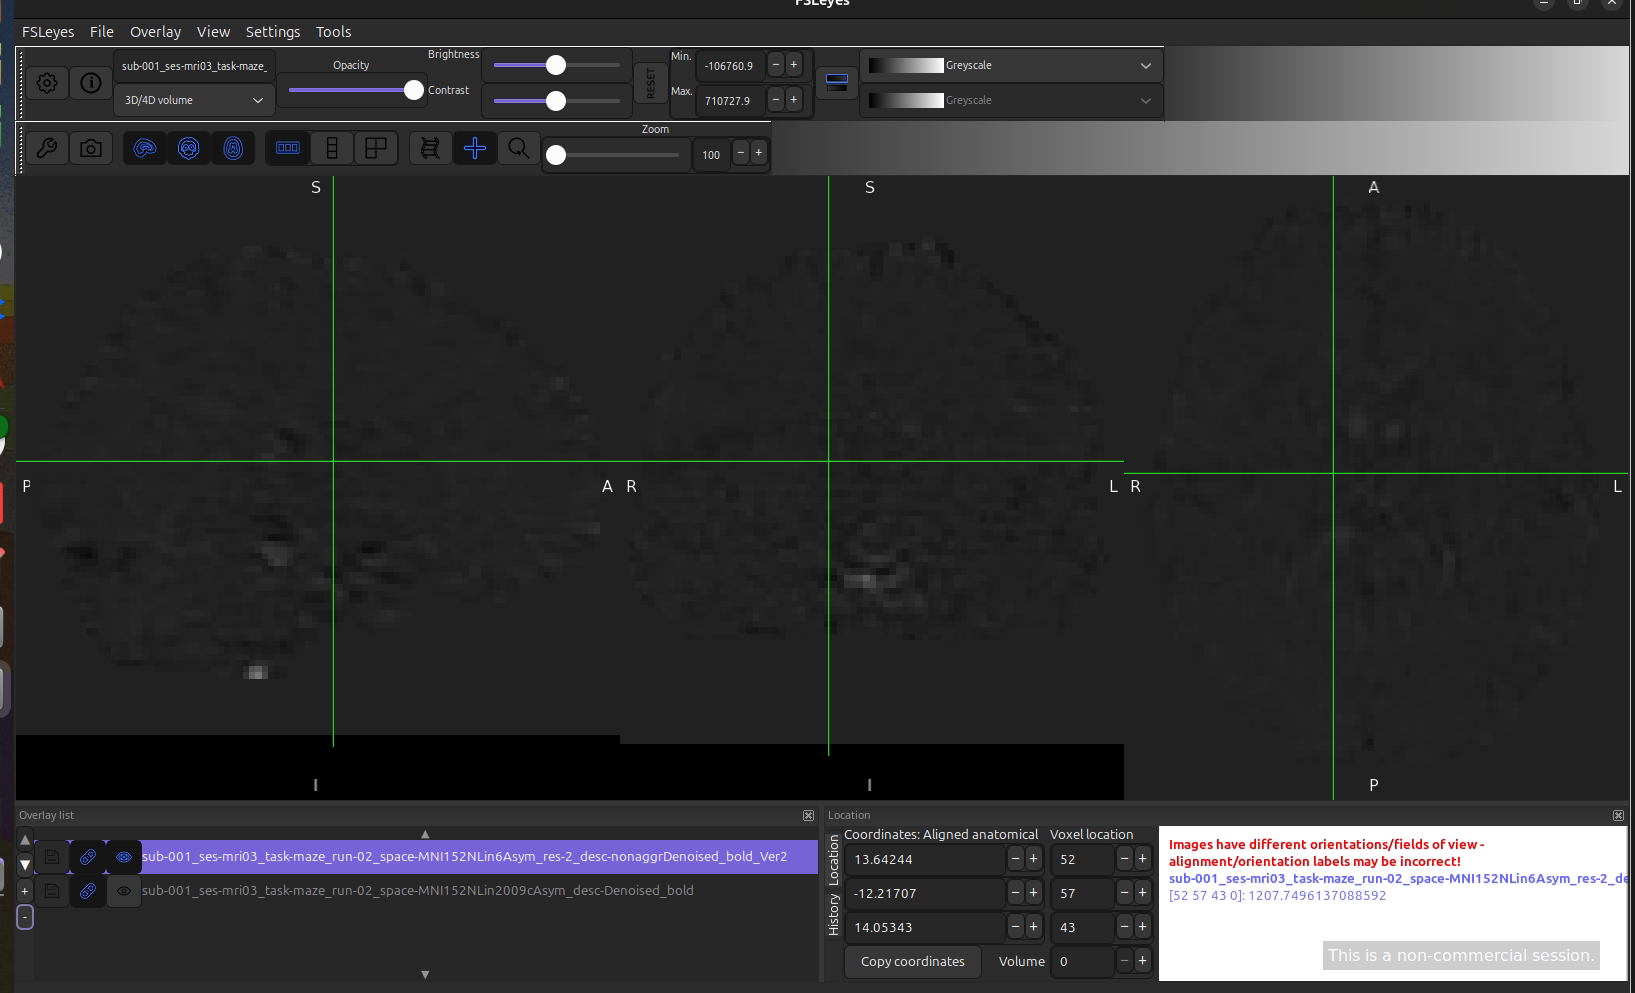
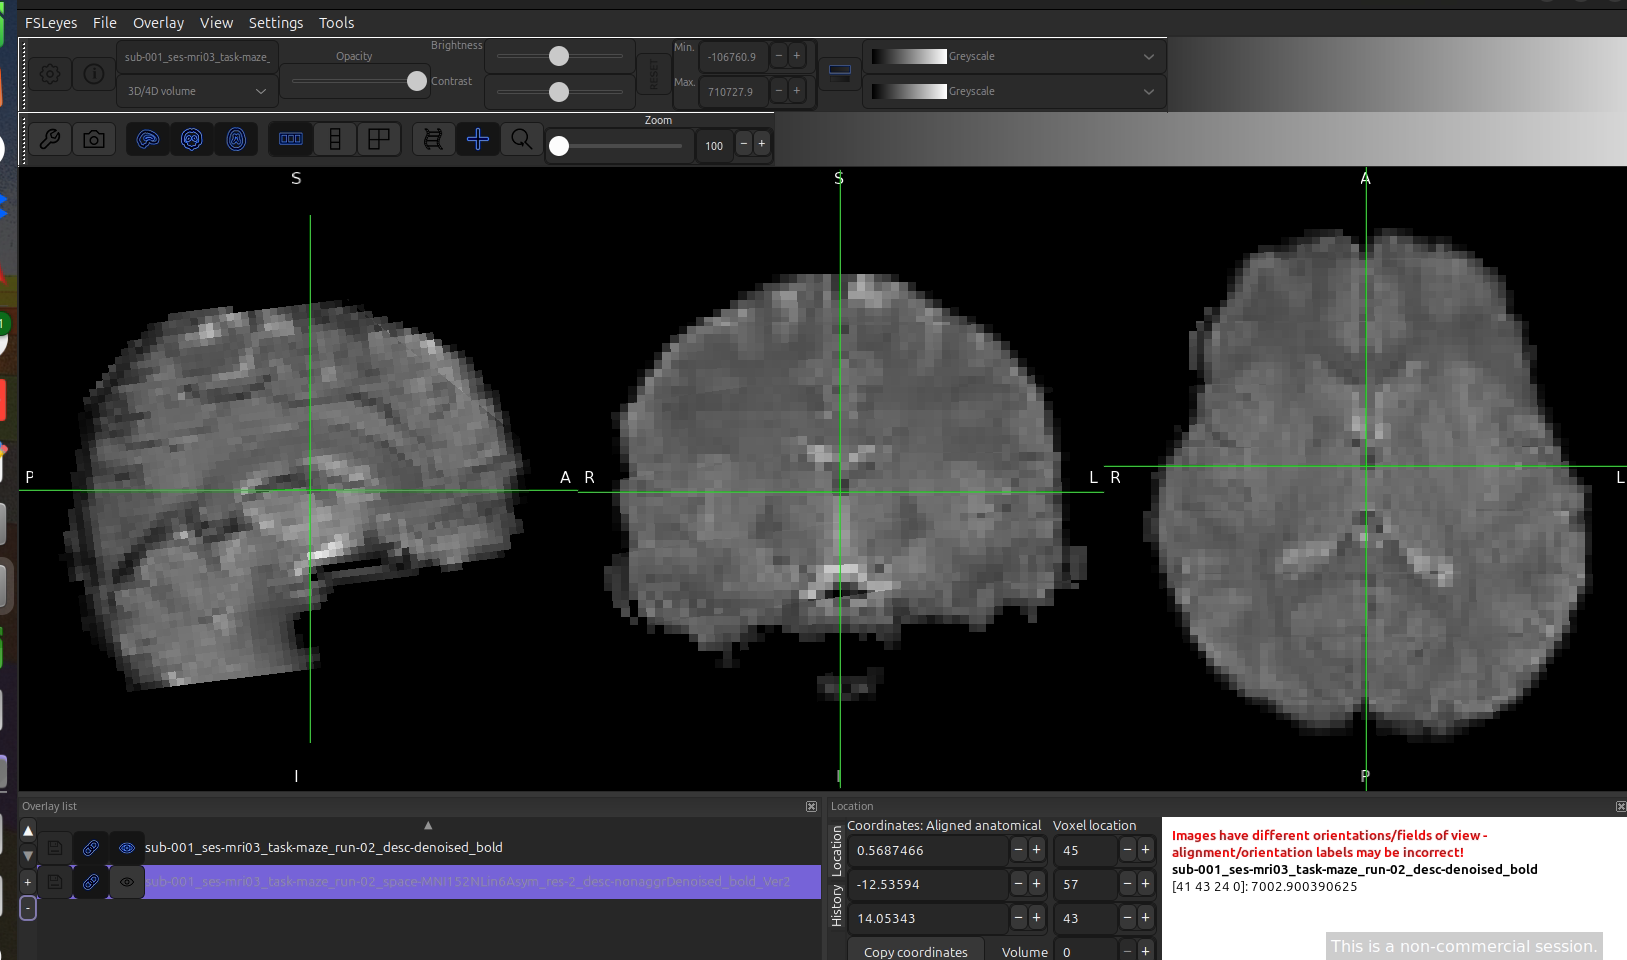
Summary of what happened:
I preprocessed my multiecho data with fMRIPrep and then denoised it using Tedana. Although I believe everything ran without errors, I noticed a significant discrepancy when inspecting the results. The optimally denoised/combined output from Tedana looks drastically different from the output I obtain when manually denoising the data with components (in my desired space). Specifically, the manual component‑based denoising produces a NIfTI file with a strange appearance and a substantially larger file size (~3 GB), compared to Tedana’s denoised output (~330 MB).
Command used (Denoising fmriperp outputs in standard space with tedana produced components):
import pandas as pd
import numpy as np  # A library for working with numerical data
from nilearn.masking import apply_mask, unmask  # Functions for (un)masking fMRI data


# Files from fMRIPrep
data_file = "/media/fmriprep_rev2/sub-001/ses-mri03/func/sub-001_ses-mri03_task-maze_run-02_space-MNI152NLin6Asym_res-2_desc-preproc_bold.nii.gz"
mask_file = "/media/fmriprep_rev2/sub-001/ses-mri03/func/sub-001_ses-mri03_task-maze_run-02_space-MNI152NLin6Asym_res-2_desc-brain_mask.nii.gz"
confounds_file = "/media/fmriprep_rev2/sub-001/ses-mri03/func/sub-001_ses-mri03_task-maze_run-02_desc-confounds_timeseries.tsv"

# Files from tedana (after running on fMRIPrepped data)
mixing_file = "/media/sub-001/ses-mri03/task-maze/run-02/sub-001_ses-mri03_task-maze_run-02_desc-ICA_mixing.tsv"
metrics_file = "/media/Elements2/tedana_rev3/sub-001/ses-mri03/task-maze/run-02/sub-001_ses-mri03_task-maze_run-02_desc-tedana_metrics.tsv"

# Load the mixing matrix
mixing_df = pd.read_table(mixing_file)  # Shape is time-by-components

# Load the component table
metrics_df = pd.read_table(metrics_file)
rejected_columns = metrics_df.loc[metrics_df["classification"] == "rejected", "Component"]
accepted_columns = metrics_df.loc[metrics_df["classification"] == "accepted", "Component"]

# Load the fMRIPrep confounds file
confounds_df = pd.read_table(confounds_file)

# Select external nuisance regressors we want to use for denoising
confounds = confounds_df[
    [
        "trans_x",
        "trans_y",
        "trans_z",
        "rot_x",
        "rot_y",
        "rot_z",
        "csf",
        "white_matter"
    ]
].to_numpy()

# Select "bad" components from the mixing matrix
rejected_components = mixing_df[rejected_columns].to_numpy()
accepted_components = mixing_df[accepted_columns].to_numpy()


# Apply the mask to the data image to get a 2d array
data = apply_mask(data_file, mask_file)

# Fit GLM to accepted components, rejected components and nuisance regressors
# (after adding a constant term)
regressors = np.hstack(
    (
        confounds,
        rejected_components,
        accepted_components,
        np.ones((mixing_df.shape[0], 1)),
    ),
)
betas = np.linalg.lstsq(regressors, data, rcond=None)[0][:-1]

# Denoise the data using the betas from just the bad components
confounds_idx = np.arange(confounds.shape[1] + rejected_components.shape[1])
pred_data = np.dot(np.hstack((confounds, rejected_components)), betas[confounds_idx, :])
data_denoised = data - pred_data

# Save to file
denoised_img = unmask(data_denoised, mask_file)
denoised_img.to_filename(
    "/media/Denoised/sub-001_ses-mri03_task-maze_run-02_space-MNI152NLin6Asym_res-2_desc-nonaggrDenoised_bold_rev3.nii.gz"
)
Screenshots / relevant information:
Manually Denoised: