Summary of what happened:
I’m running micapipe 0.2.3 on Rocky Linux 8.10 to process structural and diffusion MRI data. The structural data was processed with no issues and the output looked fine. The dMRI processing worked for some subjects but failed for others, apparently because dwifslpreproc failed because libcudart.so.9.1 cannot be found for these subjects.
There is no difference in the acquisitions, the only difference is that since I’m running this on an HPC, each subject is processed on a different CPU node. The odd thing is that when I rerun the structural processing for these subjects, and then rerun the dMRI processing, it often works fine. I’d like to get to the bottom of this because I can’t keep rerunning half the subjects all the time, does anyone have an idea what I could check?
Command used (and if a helper script was used, a link to the helper script or the command generated):
singularity run --writable-tmpfs --containall \
 -B /rds/project/rds-nCu8GHKxWRw/data/micapipe:/rds/project/rds-nCu8GHKxWRw/data/micapipe \
 -B ${bids_dir}:${bids_dir} \
 -B ${out_dir}:${out_dir} \
 -B ${temp_dir}:${temp_dir} \
 -B /rds/project/rds-nCu8GHKxWRw/data/micapipe/work_dir:/tmp \
 -B /rds/project/rds-nCu8GHKxWRw/data/micapipe/dwifslpreproc:/opt/miniconda-22.11.1/envs/micapipe/bin/dwifslpreproc \
 -B /rds/project/rds-nCu8GHKxWRw/data/micapipe/work_dir/.mrtrix.conf:/etc/mrtrix.conf \
 -B /usr/local/software/spack/spack-git/opt/spack/linux-rhel7-broadwell/gcc-5/ants-2.3.4-lj6vm7ccmij4yywr4ynrttcko4aoflqt/bin:/opt/ants-2.3.4 \
 -B /rds/project/rds-nCu8GHKxWRw/data/micapipe/license.txt:/opt/freesurfer-7.3.2/license.txt \
/rds/project/rds-nCu8GHKxWRw/data/micapipe/micapipe-v0.2.3.simg \
-bids ${bids_dir} \
-sub ${subj} \
-out ${out_dir} \
-ses ${session} \
-tmpDir /rds/project/rds-nCu8GHKxWRw/data/micapipe/work_dir/${subj}_${session} \
-fs_licence /opt/freesurfer-7.3.2/license.txt \
-proc_dwi -rpe_all \
Version:
<micapipe 0.2.3>
Environment (Docker, Singularity / Apptainer, custom installation):
Data formatted according to a validatable standard? Please provide the output of the validator:
PASTE VALIDATOR OUTPUT HERE
Relevant log outputs (up to 20 lines):
               ============
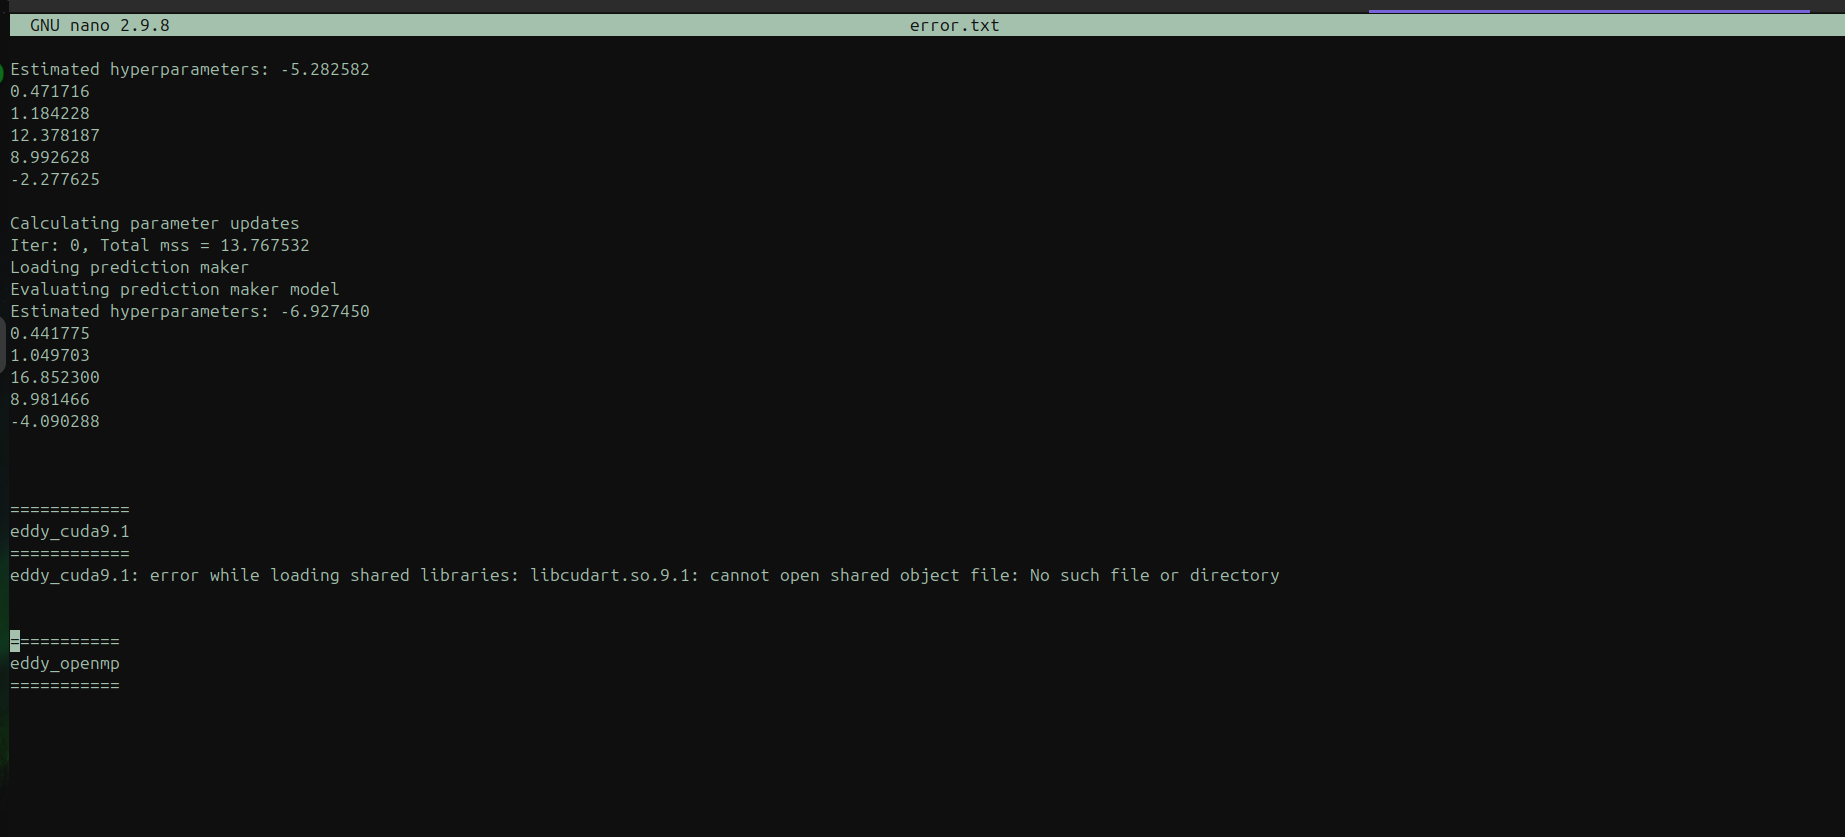
               eddy_cuda9.1
               ============
               eddy_cuda9.1: error while loading shared libraries: libcudart.so.9.1: cannot open shared object file: No such file or directory

               ===========
               eddy_openmp

dwifslpreproc:
dwifslpreproc: [ERROR] For debugging, inspect contents of scratch directory: /rds/project/rds-nCu8GHKxWRw/data/micapipe/work_dir/sub-CISC39120_ses-20260810/4150_micapipe_proc-dwi_CISC39120/dwifslpreproc-tmp-SF6LWV/
dwifslpreproc: Scratch directory retained; location: /rds/project/rds-nCu8GHKxWRw/data/micapipe/work_dir/sub-CISC39120_ses-20260810/4150_micapipe_proc-dwi_CISC39120/dwifslpreproc-tmp-SF6LWV/

-------------------------------------------------------------
[ ERROR ]..... dwifslpreproc failed, check the logs
Screenshots / relevant information:
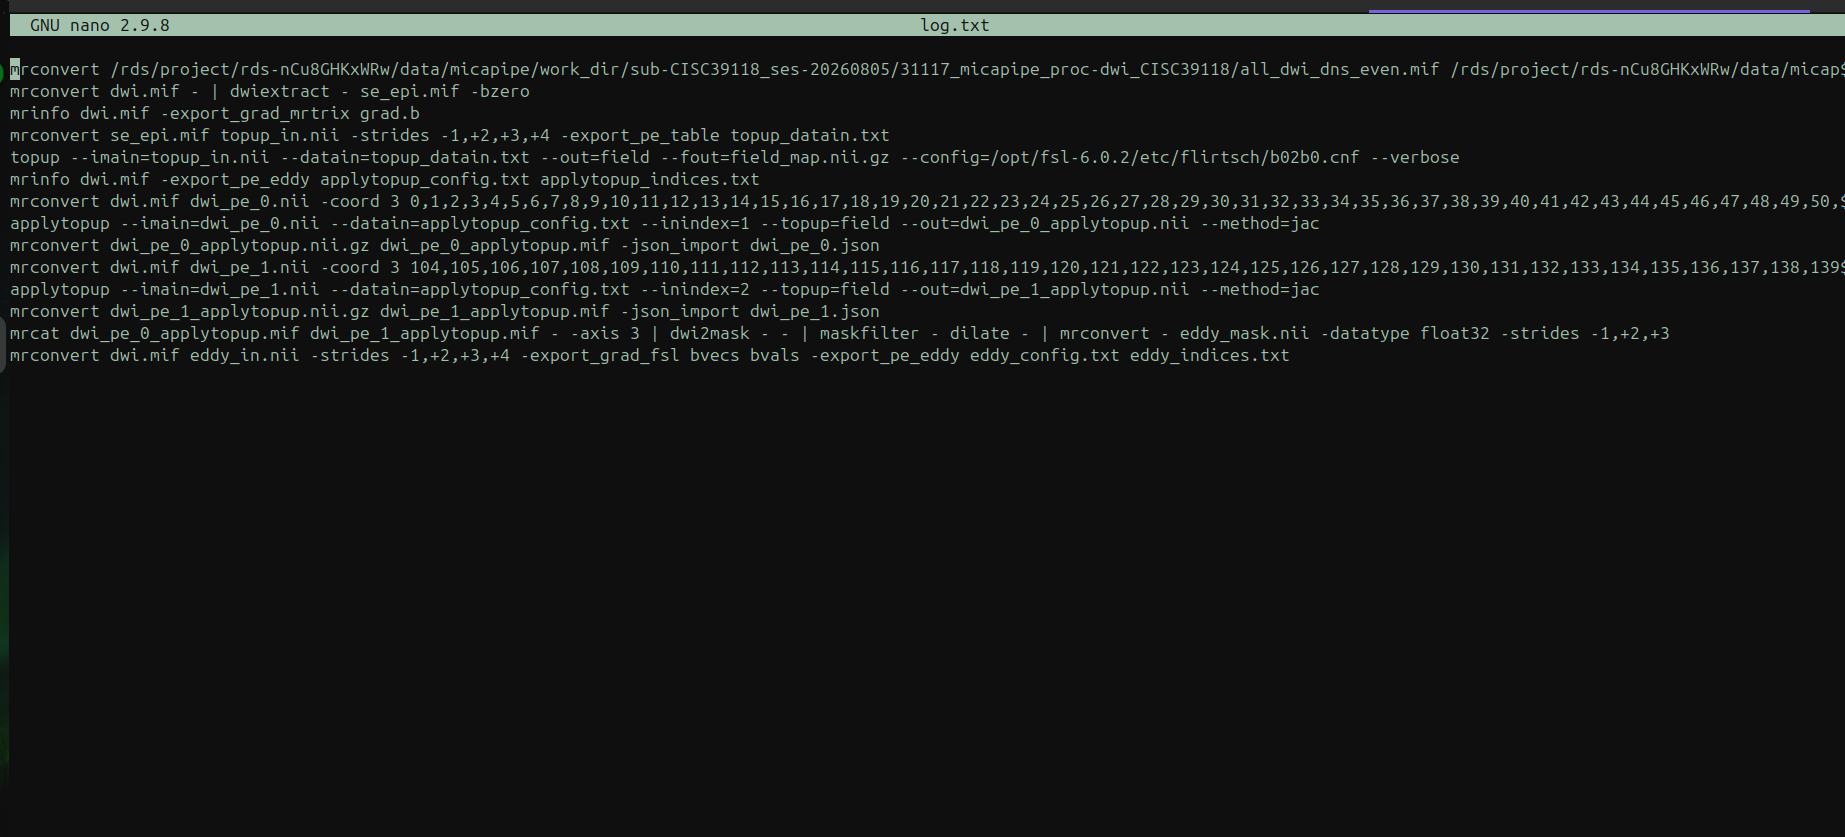
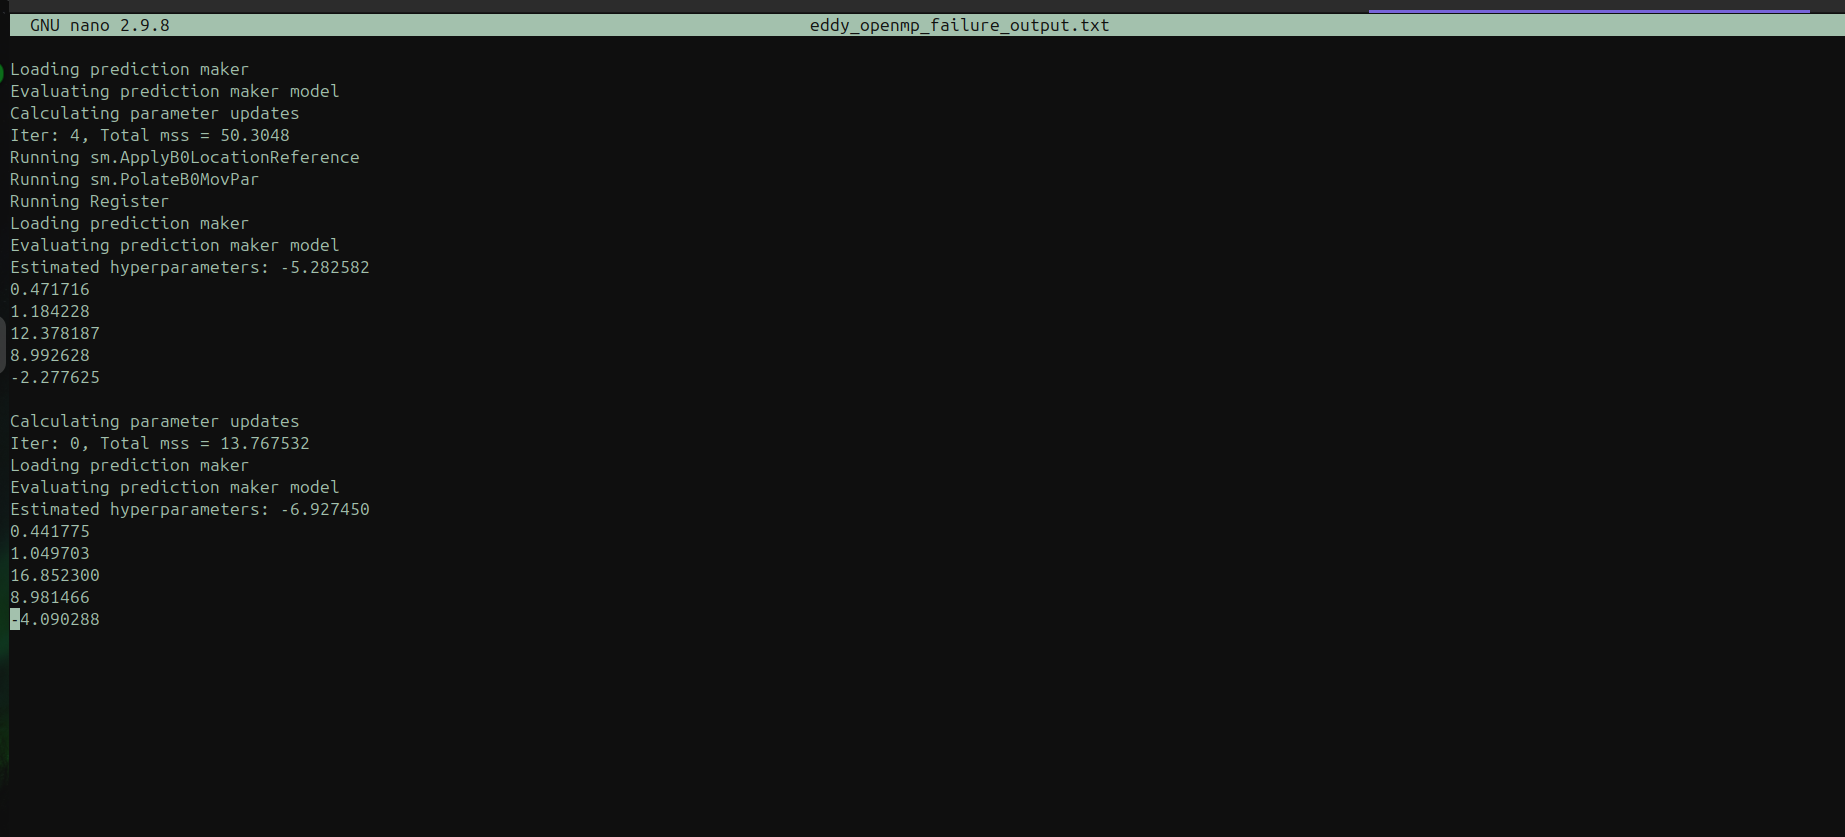
Attached: Outputs from retained scratch directory (log.txt, error.txt, eddy_openmp_error_output.txt)